“They get more views” doesn’t tell us what to film next. A useful competitor study compares the same window and similar formats, then asks which viewer problems each creator helps solve. We’ll use a keyboard-review channel as an example, with our own test setup providing the original contribution.
Kabo, an AI agent for creator research, supplies the public comparison sample; Codex helps decide which series our own channel should make next.
Prepare the series options and test constraints
[ ] channels.md — 3 real public channel URLs and why each is a relevant peer.
[ ] rubric.md — Definitions for topic, format, test method and sponsorship disclosure.
[ ] scope.md — Shared start/end dates; Shorts and livestream handling.
[ ] our-advantage.md — Tests, access or expertise we can supply ourselves.
[ ] research/ — Raw source rows; keep these separate from positioning.md.
Connect Kabo inside the project
Install Kabo in Codex, complete sign-in and open a new task so the tools refresh. Keep the task in the content folder named below.
Write the series decision before building the comparison
Our keyboard reviewer can record repeatable sound tests, but has limited filming time. Before collecting, state the decision: do we make another product roundup, an environment comparison or a build stream? Define what evidence would make each option useful to our viewers.
This is a personal production choice. We need a consistent comparison, but not a long exercise in negotiating a team codebook.
Read our-advantage.md and the channel brief. Compare 3 possible next-series directions: buying roundup, workspace sound comparison and build stream. For each, state the viewer decision, proof we can supply and what the competitor sample would need to show. Then propose a small comparable collection scope for channels.md.
Collect channel evidence with coverage notes
Ask Kabo’s ready public tools for the relevant uploads. Keep pagination limits and actual included counts for each channel. A topic search can find examples, but it does not establish a complete channel inventory. Store source URLs and dates in competitor-sources.csv, separate from your editorial interpretation.
A positioning decision rather than a channel ranking
Imagine our advantage is recording the same keyboard in different rooms. A useful positioning note might look like this:
- Proposed series: One keyboard, three everyday workspaces
- What we contribute: Our own controlled recordings and desk constraints.
- Comparison needed: Which sampled channels test environments explicitly?
- Do not fill yet: Competitor upload counts or performance differences.
- Approval gate: Inspect the source rows before accepting a “gap.”
Compare the evidence against the three options
Keep publication window and format comparable. Then ask what each accepted source actually helps its viewer decide, and whether our own test could add something specific. An example that says “best keyboard” does not establish that it demonstrates different rooms. Leave that evidence check open.
A useful output may recommend a limited pilot even when the sample cannot establish a content gap. The proposed series is our editorial decision, not a missing category proved by a partial search.
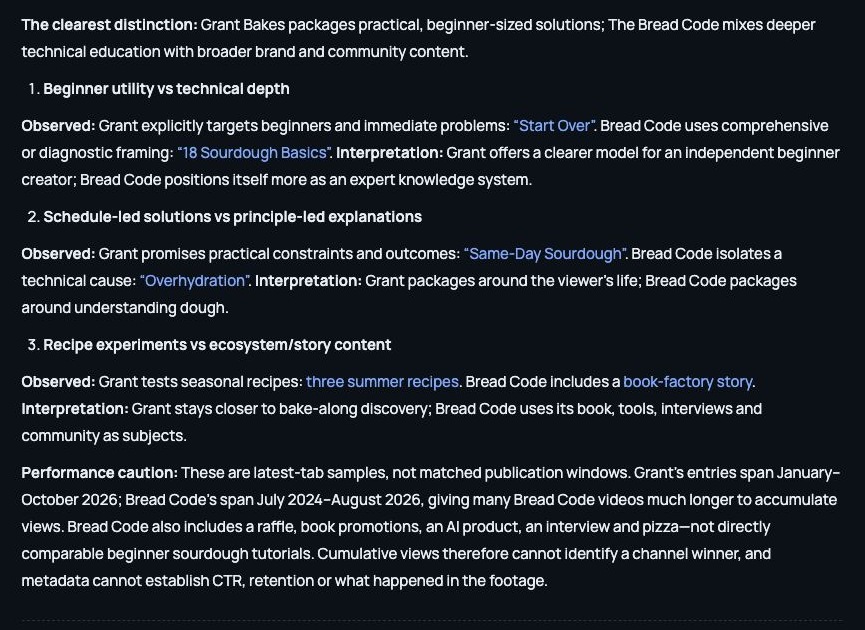
Using the reviewed public source rows, compare our 3 series options. Attach source observations to each advantage or concern, mark coverage limits and separate unknowns from absence. Recommend one feasible pilot using our quiet-room access and controlled recordings. Save positioning.md with the chosen test, what to film and the assumption we should check after the pilot. Keep metric snapshots in competitor-sources.csv.
Choose a pilot and its stop condition
For the workspace comparison, record the same keyboard and passage in the environments we can document. Decide what would make the pilot unusable: mismatched settings, unclear context or no meaningful demonstration. This gives us a production test rather than a prediction about views. Refresh the comparison later only if a new series decision needs it.
You grouped build livestreams with edited reviews. Split those formats, recompute only the affected summaries and show which positioning conclusions still hold.
Take the chosen workspace test into a pilot
Review the three options in Google Sheets, then take only the chosen test into a brief. Use the script workflow once its proof is planned.
For a team that needs to agree on category definitions before a larger study, the Claude Code comparison guide focuses on that calibration job.
Worked examples are illustrative. Product screenshots show existing Kabo web results, not a run of the example in this guide. Use your own materials and the evidence returned in your task.