A shortlist can look convincing while its most important comparison is still unresolved. Big public counts do not tell us whether a Reel exceeded that account’s usual performance. Let’s inspect the returned baseline states before ranking anything.
We’ll use Kabo, an AI agent for creator research, from a compatible MCP client to inspect or enrich a relevant Reels sample. Our example is a pet-education shortlist. If we have no candidates yet, there is a compact collection step below; the main job here is deciding what the returned evidence actually lets us compare.
1. Read the unresolved row before sorting the table
Suppose an enrichment result contains a relevant training demonstration but no usable account baseline. The example below describes an authored case, not a real tool response:
- Relevance: useful to our teaching question.
- Baseline evidence: insufficient.
- Outlier multiple: unresolved, not zero.
- Decision: keep as an explanation reference; do not rank as an account-relative winner.
Those are two different judgments. We can want to inspect the demonstration without claiming it is a breakout Reel.
Review [returned shortlist]. For each row, separate topic relevance from eligibility for an account-relative comparison. Inspect returned exact-detail and baseline states. Preserve null or unresolved values. Return compare / reference-only / needs-evidence with a reason and actual source reference. Do not infer a missing multiple from view count.
Bring the shortlist receipt, not just the captions
[ ] Topic and relevance rules — A specific teaching question and language/format.
[ ] Publication window — Start/end dates, separate from retrieval date.
[ ] Candidate receipt — Actual candidate_set_id, content_key values, status and coverage.
[ ] Selection notes — Accepted items and the reasons for semantic relevance scores.
[ ] Output destination — Copyable evidence table or an authorized local file.
Use a client that can retain the candidate identifiers
Connect https://kabo.sh/mcp-pub in a compatible client and complete Kabo sign-in. The MCP setup guide covers the connection; installation options are available for Codex and Claude Code.
Here we use a conversation-oriented MCP client with the remote tools connected. It only needs to return a copyable table; filesystem access is optional. Inspect the ready Kabo tools before asking for the shortlist.
2. Recover the missing evidence only when it changes the choice
If the question really needs an account-relative comparison, inspect the current enrich_instagram_shortlist schema and use the accepted candidate_set_id and content_key values. Retain the required platform, ranking_mode, window and semantic_scores inputs. Relevance scores are editorial judgments, not predicted performance.
If the returned baseline remains insufficient, stop treating that row as comparable. An identifier mismatch needs resolution from the actual receipt; a plausible replacement ID is not a fix.
Inspect the current enrich_instagram_shortlist schema. Use the saved candidate_set_id and accepted content_key values with required platform/ranking_mode/window fields and supported semantic_scores. Explain relevance judgments. Inspect exact_detail_status, baseline_status and outlier_multiple. Report unresolved comparisons and identifier mismatches; do not replace missing values or fabricate handles.
3. No saved candidate set? Make a small one first
Use collect_instagram_trend_candidates for the specific teaching question, language and publication dates, then review the returned candidates. Preserve the candidate-set receipt and select only useful rows for the enrichment step above. Do not enrich everything just because it was returned.
The MCP overview explains connection and tool readiness. The YouTube dossier guide covers a full discovery-first research session on that platform.
Inspect collect_instagram_trend_candidates inputs. Collect for [teaching question], [language/format] and [start/end dates] with a small supported intent plan and budget. Preserve actual candidate_set_id, content_key values, URLs, status and limitations. Return a relevance review before proposing enrichment. Do not describe a partial set as a complete inventory.
4. Hand off two useful views of the same sample
Return a comparable subset for the rows whose evidence supports the chosen account-relative comparison, and a reference-only subset for relevant examples that do not. Keep publication dates, retrieval dates and returned limitations with both.
A useful row does not need to win a ranking. The pet educator may choose the clearest demonstration from the reference-only group, then inspect the original before planning their own version.
content_key,source_url,published_at,retrieved_at,exact_detail_status,baseline_status,outlier_multiple,editorial_relevance,comparison_status,limitations
This row has insufficient baseline evidence and an unresolved outlier multiple. Keep the returned values, remove its relative ranking and place it in the reference-only subset if still relevant. Explain the evidence needed to make it comparable. Do not rerun collection unless our scope changes.
Choose a reference for the right reason
Review the two subsets in Google Sheets or copy them from the client. Use the Muse shortlist guide to discuss a debatable selection, or the MCP content-ideas guide to turn an accepted reference into an original brief. Keep the snapshot date with the table when sharing it.
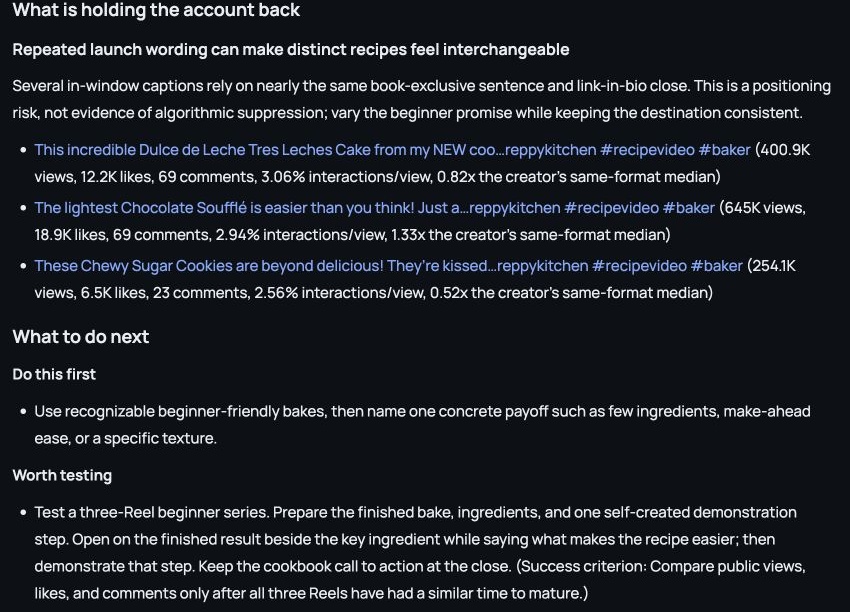
Worked examples are illustrative. Product screenshots show existing Kabo web results, not a run of the example in this guide. Use your own materials and the evidence returned in your task.